The series assumes no prior graph database expertise.
What Is a Graph?
A graph is a set of things and a set of connections between them. That is the whole definition.
The things are called vertices (or nodes) and the connections are called edges (or relationships).
Formally, a graph $G $ is modeled as a tuple $(V, E)$, where $V $ is a set of vertices and $E $ is a subset of the Cartesian product of $V $ with itself, representing a set of edges:
$E \subseteq V \times V$
We find 3 kinds of graphs: directed, undirected, and weighted.
-
For a directed graph, an edge $E $ equals the ordered pair $(u, v)$ in $E $, where $u $ is the source vertex and $V $ is the destination vertex; an example is a Twitter follow, where the relationship has a specific direction:
edge $e = (u, v) \in E$ -
For an undirected graph, an edge $E $ is an unordered pair containing $u $ and $V $ in $E $; an example is a Facebook friendship, where the relationship is mutual:
edge $e = \{ u, v \} \in E$ -
A weighted graph extends this structure as a triple $(V, E, w)$, where $w $ is a function that asigns each edge in $E $ a real number (a weight), which is useful for representing distances, costs, or strengths:
triple $(V, E, w)$ where $w: E \to \mathbb{R}$
What Can Be a Graph?
The power of the graph model lies in its universality. Once you start looking, graphs are everywhere.
- Social networks represent friendship, followership, and interaction as edges connecting user vertices.
Does Alice know Bob through other people?
Is basically walking the graph and finding this relationship.
-
Fraud detection systems model transactions and accounts as graphs, exploiting the fact that fraudulent rings are just cycles or dense cluster of accounts and transactions.
The relationships between entities often reveal fraud more reliably than the entities themselves. -
Supply chain and logistics applications use graphs to model dependencies between suppliers, warehouses, and shipments.
-
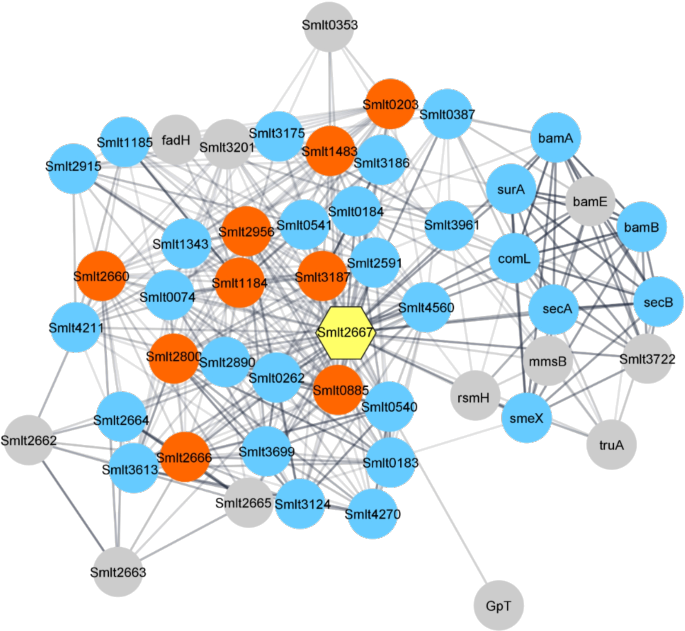
Biologists represent protein interaction networks and drug-target relationships.
-
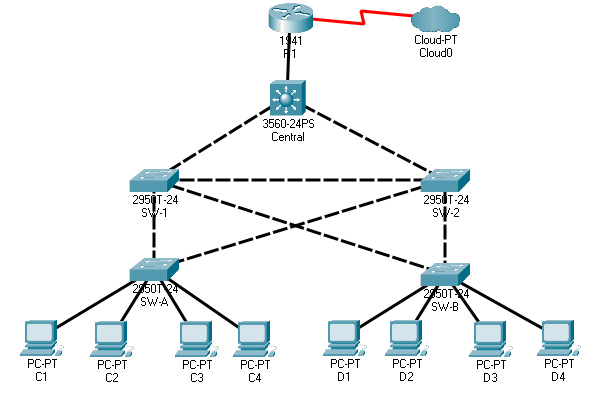
Networks use graphs to represent topologies.
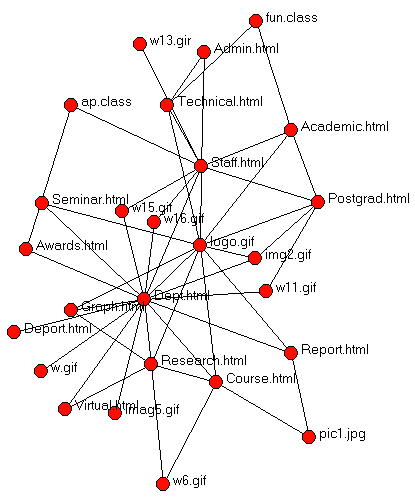
- The web is another example.
Pages are vertices, hyperlinks are directed edges, and the resulting graph is one of the largest and most studied structures in computing:
Modeling as a graph
What the above domain examples share are Properties that make a Graph an intuitive solution for us human beings. Relationships are as important as the entities themselves.
The schema is often irregular or evolving. Queries frequently follow chains of connections whose length or shape is not known in advance.
Graphs are also effective because they are easy to reason about visually. Human beings understand things better with examples, and a graph makes relationships explicit. That visual and structural clarity often translates into data models and algorithms that are easier to explain, and question.
The model defined at the start of this post, a set of vertices and a set of edges with no data attached to either of them, underlies much of classical graph theory and is the basis for graph processing frameworks and graph database management systems. It is, however, too limited for most real-world database scenarios, because it carries no information beyond structure. The richer models used in graph databases are built on top of it.
- The Labeled Property Graph (LPG) is the standard conceptual model used by most graph database systems. It enriches the simple graph with two mechanisms: labels, which classify vertices and edges into types, and properties, which attach arbitrary key-value data to individual vertices and edges.
A vertex might have the labelPersonand propertiesname='Alice' and age=21.
An edge might have the labelKNOWSand a propertysince = "09.08.2007".
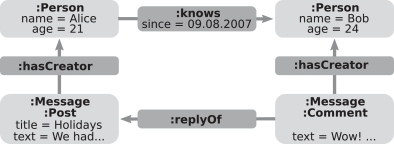
There are other variants of LPG implemented by others systems with minor extensions or restrictions, Neo4j for example supports an arbitrary number of labels per vertex but restricts edges to exactly one label.
- The Resource Description Framework (RDF) takes a different approach. RDF represents information as collections of triples subject, predicate, object $(s, p, o)$.
While RDF-based systems are a meaningful part of the graph database landscape, they follow a different data model than LPG and are outside the scope of this series. We mention it only for context, as this article series is focused on labeled property graph databases.
The Many Forms of Graph Databases
The graph database landscape is heterogeneous. Systems differ fundamentally in how they store graphs, what data models they support, and what query languages they expose.
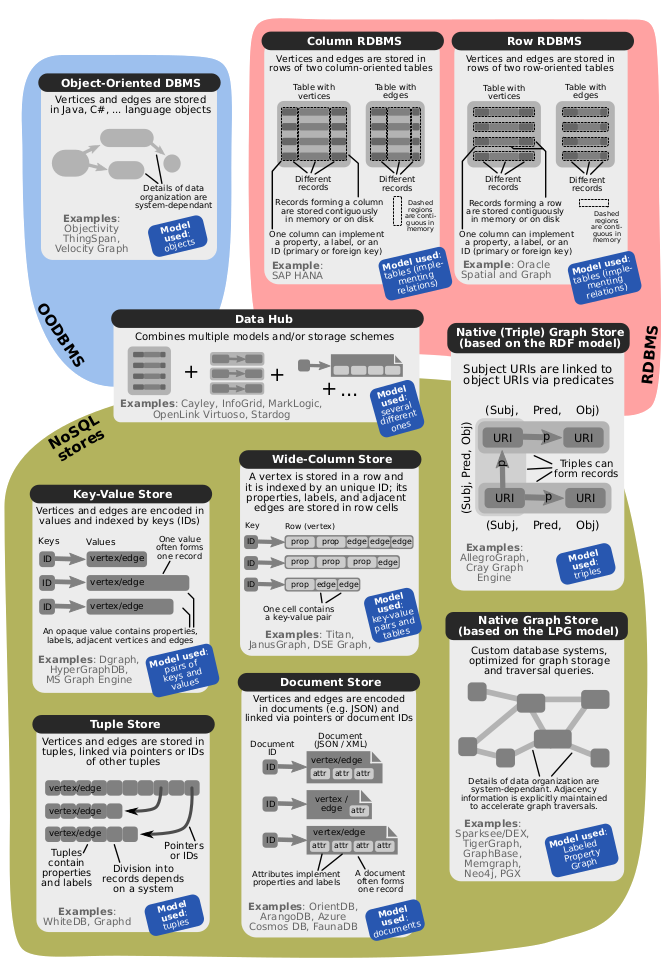
Native graph databases are built from the ground up around the graph model. Their storage layouts and query engines are designed with graph access patterns as the primary concern: they aim to “follow pointers”, or otherwise access adjacency directly, so that traversal “does not become a JOIN”.
Neo4j is the most prominent example. For a long time its storage engine used fixed-size records with direct pointers between them, and this design was mostly how people described native graph storage.
After nearly 15 years, in 2024, Neo4j introduced a block format that colocates related data into variable-length blocks inside pages [1]. Although a late realization (for the better), it implies that “native equals pointer chasing” description is no longer fully accurate.
The useful definition therefore should be behavioral, meaning native systems try to make adjacency access direct, whether through pointers, colocated blocks, or other graph-specific layouts.
Non-native graph databases take an existing mature backend; a relational, document or key-value store and build graph capabilities on top of it [2]. Both classes are graph databases in the sense that they store, query, and manage graph data, but their internals are fundamentally different implying which graph-specific optimizations are available and which are left to the backend.
In practice, the difference is more about where the engineering effort goes, for example non-native systems inherit decades of work in concurrency control, indexing, query optimization and many other DBMS components.
A survey of approximately one hundred graph database systems reveals that roughly 66% are non-native. The distribution of underlying data models breaks down as: 34% native graph storage, 24% relational databases, 24% key-value or wide-column stores, and 18% document stores. This makes sense, one would want to make an existing DBMS capable of supporting graph queries if possible, providing users with the best possible interface.
This is precisely where PostgreSQL enters the picture. As a mature relational database, it represents a massive share of that non-native ecosystem through extensions and new SQL standards.
Key Takeaways
Before we jump into the technical implementation, let’s lock in the core concepts from this introduction:
- Graphs are universal: At their core, they are just vertices (nodes) and edges (relationships), making them ideal for complex, interconnected data like social networks or fraud rings.
- LPG is the industry standard: The Labeled Property Graph model extends simple graphs by allowing you to attach labels and key-value properties to both nodes and edges.
- Native vs. Non-Native is behavioral: Native databases (like Neo4j) optimize for direct adjacency access, while non-native databases leverage existing enterprise-grade engines (relational, document) to handle graph workloads.
- The landscape is hybrid: Over 66% of graph database solutions are built on top of non-graph backends, proving that you don’t always need to deploy a new native database to query graph structures.
What’s Next?
Now that we have the foundational vocabulary down, we can explore how to bring this model into the relational world. In Part 1, we will dive straight into SQL/PGQ in PostgreSQL: what this new standard brings to the table, how it is implemented under the hood, and its current limitations.